Cost Reduction
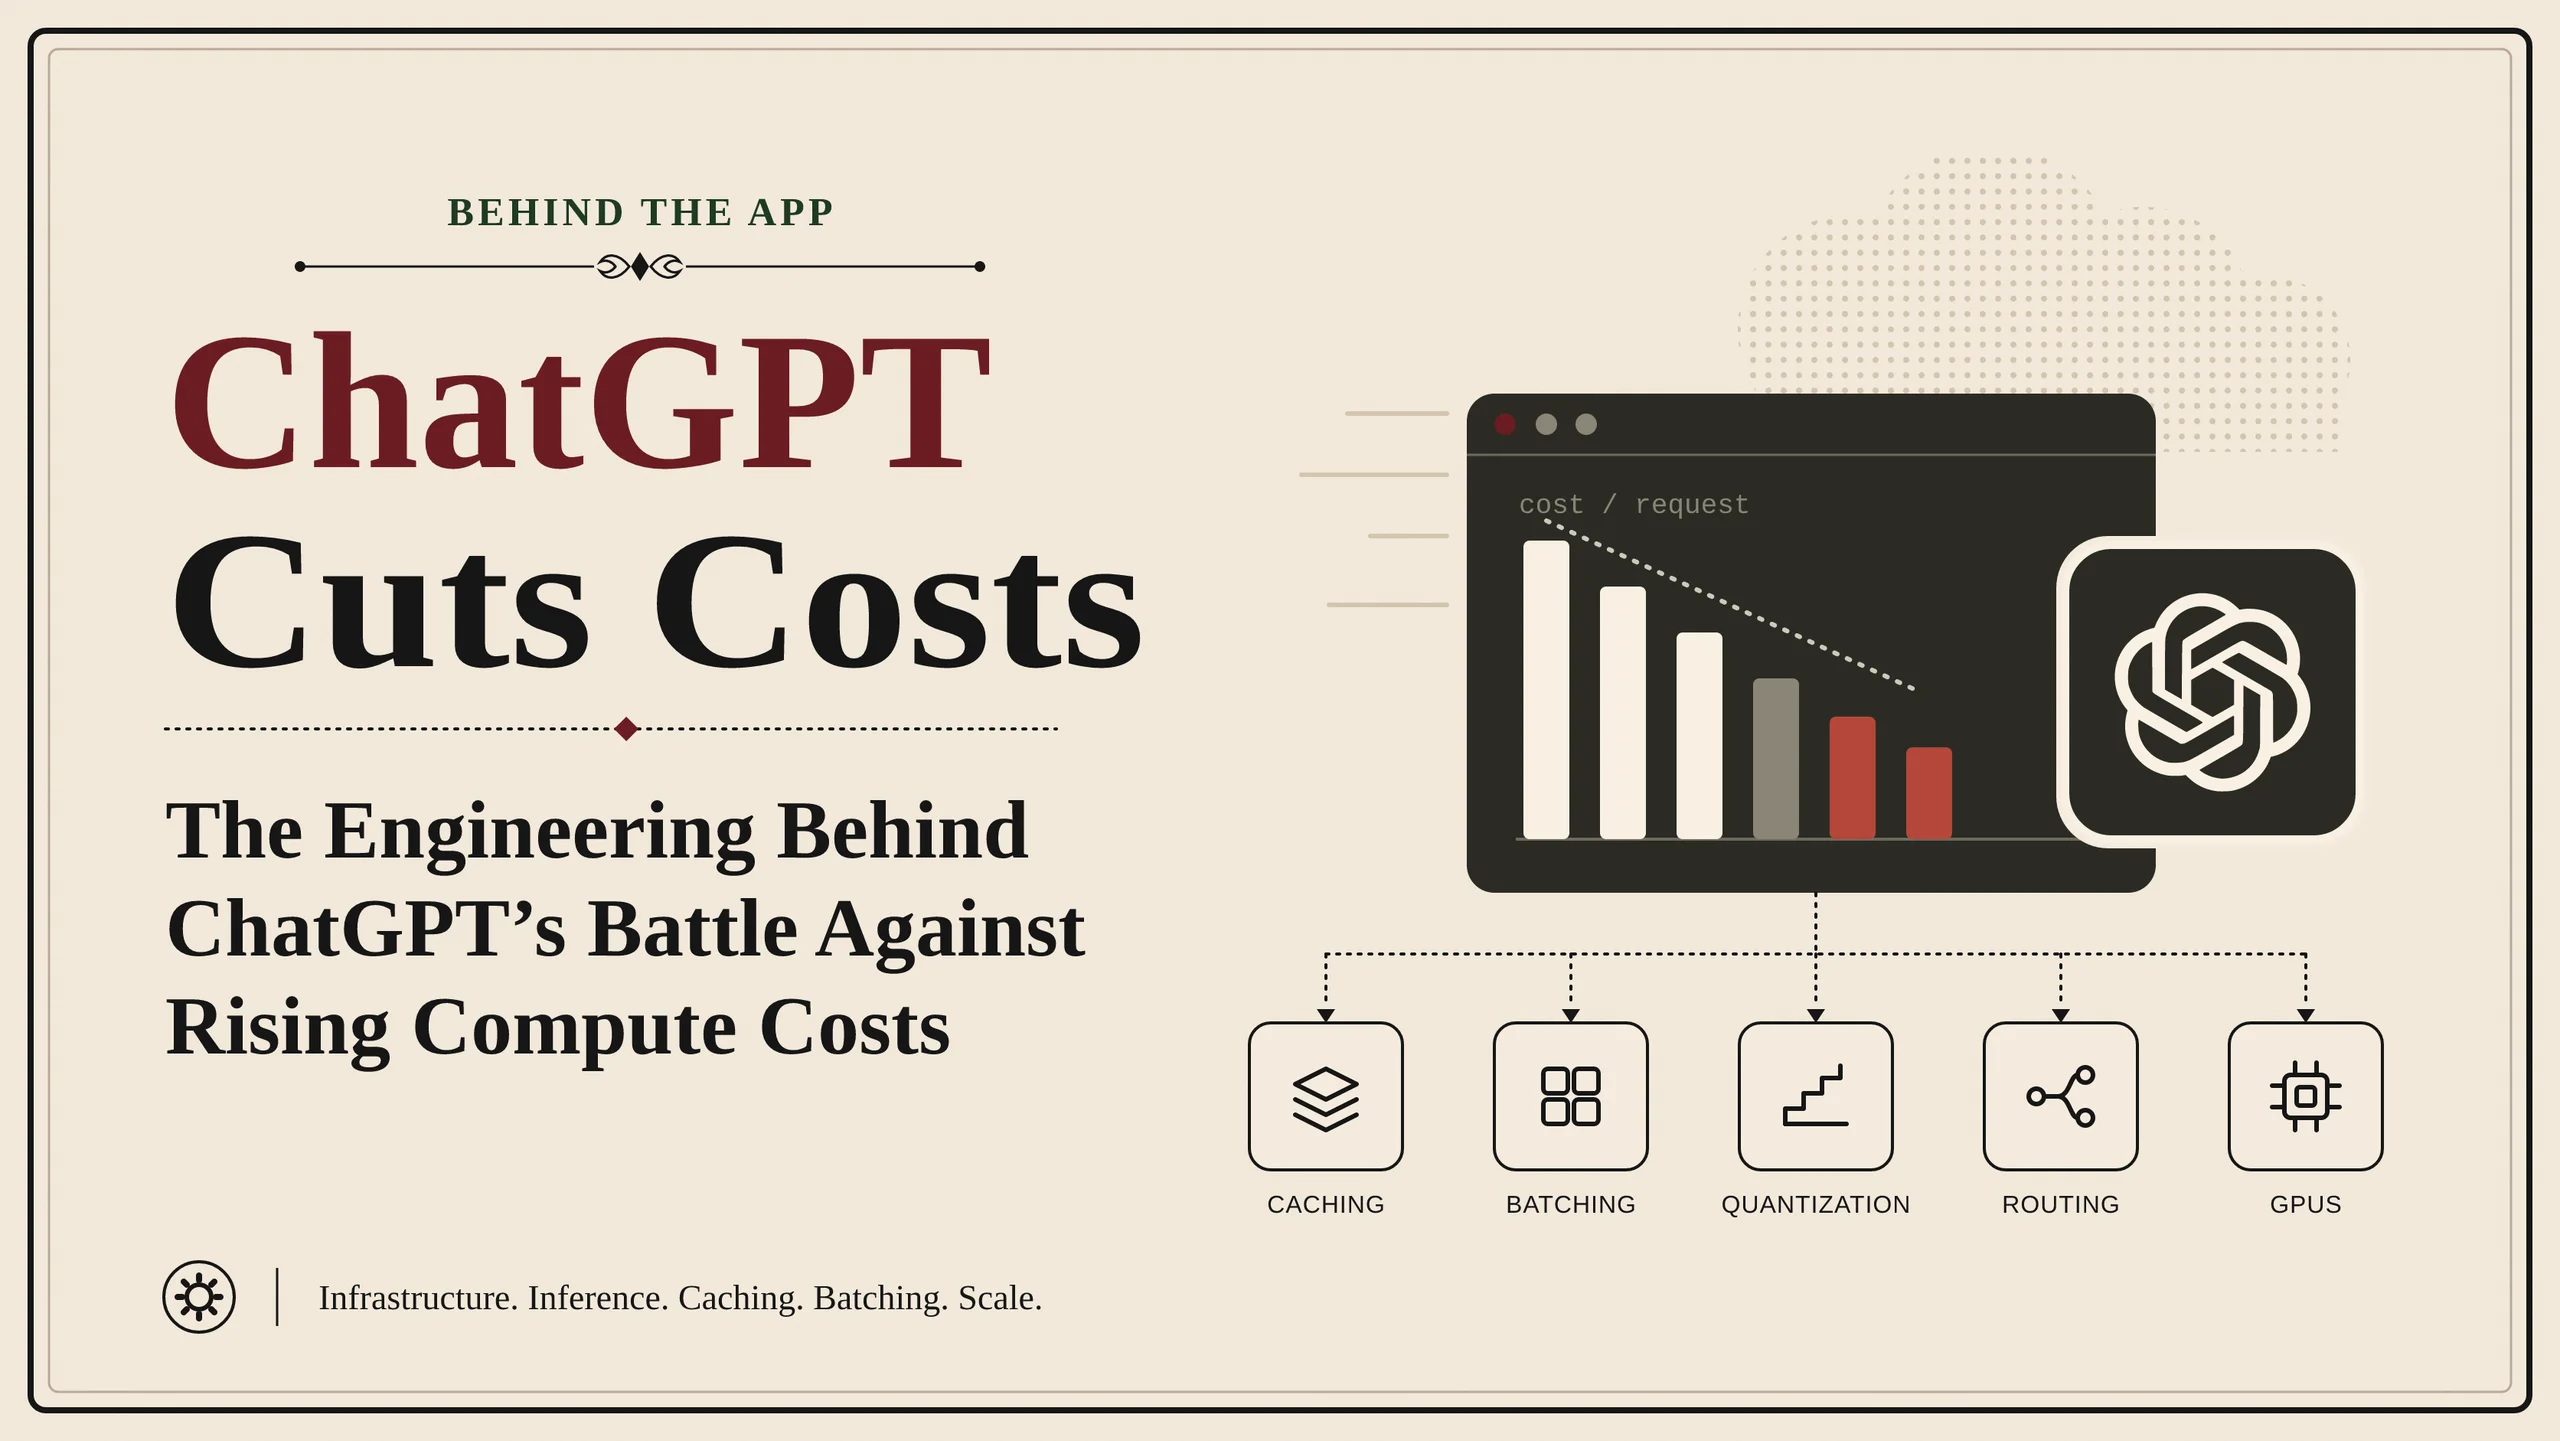
How ChatGPT Cuts Infrastructure Costs: The Engineering Behind ChatGPT's Battle Against Rising Compute Costs
OpenAI's ChatGPT triumphs over exploding compute costs through Mixture-of-Experts (MoE) architecture that activates only a fraction of its trillion-plus parameters per token, aggressive quantization, advanced KV cache management with paging and prefix caching, continuous batching for high GPU utilization, and speculative decoding. These optimizations, plus recent 2026 software wins cutting inference costs by over 50%, enable affordable, high-quality real-time responses at massive scale
Read →